
Key Takeaways
- NGS sequences many DNA or RNA fragments in parallel, whereas Sanger sequencing reads one template per reaction.
- Short-read and long-read platforms involve tradeoffs in read length, per-base accuracy, throughput, and cost.
- Sequencing accuracy depends on the full pipeline, including sample quality, coverage depth, and bioinformatics.
- Sample composition affects what a sequencing result represents, so targeted sample preparation can matter for heterogeneous tissue.
What Is Next-Generation DNA Sequencing?
NGS is a massively parallel approach to sequencing. Nucleic acids are fragmented, prepared as a library, and read simultaneously on a sequencing instrument. Software then aligns the reads to a reference genome or assembles them.
Sanger sequencing, the first-generation method, uses chain-terminating nucleotides and reads one DNA template per capillary (Sanger method review). It remains accurate for single targets but has limited throughput for genome-scale work.
The core NGS principle has three stages:
- Fragment the DNA or RNA into short pieces.
- Sequence the fragments in parallel.
- Reconstruct the sequence by aligning reads to a reference or assembling them.

The National Human Genome Research Institute (NHGRI) tracks sequencing costs over time. Its data show a steep decline in cost per genome after second-generation platforms entered wide use around 2008 (NHGRI cost data).
NGS is also called high-throughput sequencing or deep sequencing. These terms overlap but are not identical. "Deep" usually refers to coverage depth, while "high-throughput" and "massively parallel" describe scale (NGS terminology review).
The Generations of Sequencing Technology
First-Generation Sequencing (Sanger)
Sanger sequencing separates fluorescently labeled DNA fragments by capillary electrophoresis. It is still used for targeted confirmation of specific variants. Its main limitation for large projects is throughput, not per-read accuracy.
Second-Generation Sequencing (Short-Read NGS)
Second-generation platforms made massively parallel sequencing practical. Most use clonal amplification, which copies each fragment many times so the signal can be detected. Common chemistries include:
- Sequencing-by-synthesis: fluorescently labeled nucleotides are incorporated and imaged cycle by cycle. Typical read lengths range from about 50 to 300 bases.
- Pyrosequencing: detects pyrophosphate release during nucleotide incorporation. Commercial pyrosequencing platforms have since been discontinued (PMC review).
- Semiconductor sequencing: detects pH changes from hydrogen-ion release during incorporation, without optical detection.
Third-Generation Sequencing (Long-Read and Single-Molecule)
Long-read platforms sequence individual DNA molecules, usually without amplification:
- Single-molecule real-time (SMRT) sequencing: reads polymerase activity in real time. A 2019 study reported consensus reads averaging 13.5 kb at 99.8% accuracy using repeated passes of each molecule (PubMed, 2019).
- Nanopore sequencing: measures changes in ionic current as DNA passes through a protein pore. A 2023 SARS-CoV-2 benchmarking study reported 98.34% average read accuracy for one chemistry version (PMC, 2023).
Long reads can improve structural-variant detection and genome assembly in repetitive regions. Earlier long-read methods had higher per-base error rates, although consensus approaches have narrowed this difference.

"Fourth-generation sequencing" has no single agreed definition. Some reviews apply it to nanopore sequencing, while others use it for methods that retain spatial sequence context.
How Next-Generation Sequencing Works: The NGS Workflow
A typical short-read NGS workflow has four stages.
Step 1: Nucleic Acid Extraction
DNA or RNA is extracted from the sample. Yield, purity, and integrity influence library preparation and downstream data quality.
Step 2: Library Preparation
Nucleic acids are fragmented, adapters are ligated to the fragment ends, and libraries are size-selected. The protocol depends on the platform and the application, such as whole-genome, exome, or RNA sequencing.
Step 3: Sequencing
For short-read platforms, the instrument amplifies library fragments and reads them in parallel. Bases are called from the detected signal in each cycle.
Step 4: Bioinformatics Analysis
Reads are quality-filtered, aligned to a reference genome, and analyzed for variants or expression. Pipeline choices affect sensitivity and specificity.
Key Applications of Next-Generation Sequencing
NGS is applied wherever many sequences must be read at once. Common research and public-health applications include:
- Cancer research: detecting somatic mutations, gene fusions, and copy-number changes in tumor samples.
- Infectious disease surveillance: in 2019, the CDC adopted whole-genome sequencing as the standard method for PulseNet foodborne-pathogen surveillance (CDC).
- Hereditary disease research: targeted panels and exome sequencing are used to study genetic variants linked to inherited conditions.
- Agricultural genomics: the 3,000 Rice Genomes Project sequenced 3,010 rice accessions and reported about 29 million single-nucleotide polymorphisms (Nature, 2018).
Advantages and Limitations of NGS
Compared with Sanger sequencing and microarrays, NGS offers several technical advantages:
- It does not require probes designed from prior sequence knowledge, unlike microarrays.
- It provides single-nucleotide resolution across the sequenced region.
- It can process many samples in parallel through multiplexing.
NGS also has limitations. Short reads can be difficult to map in repetitive regions. Library preparation can introduce amplification bias. Data analysis requires substantial computing resources and validated pipelines.
Accuracy Depends on the Whole Pipeline
Per-base quality scores and variant-call accuracy are different metrics. A Q30 score indicates an estimated base-call error rate of 1 in 1,000, but it does not describe end-to-end variant detection.
Coverage depth also matters. A 2021 clinical whole-genome sequencing study reported that single-nucleotide variant sensitivity plateaued near 40x coverage (PMC, 2021). In that study, higher depth did not bring accuracy to 100%, so filtering and pipeline design remained important.
Sample Composition and Targeted Sample Preparation
A sequencing result reflects the material that entered the library. In heterogeneous tissue, such as tumor sections containing stromal and immune cells, bulk extraction mixes signals from several cell populations. This can dilute variants or expression signals present in a minority population.
Laser capture microdissection (LCM) is one way to address this. LCM is a microscopy-guided method for isolating selected cells or tissue regions before nucleic-acid extraction. It keeps the molecular sample linked to the morphology that guided its selection. LCM is lower-throughput than bulk extraction and requires suitable staining and slide preparation.
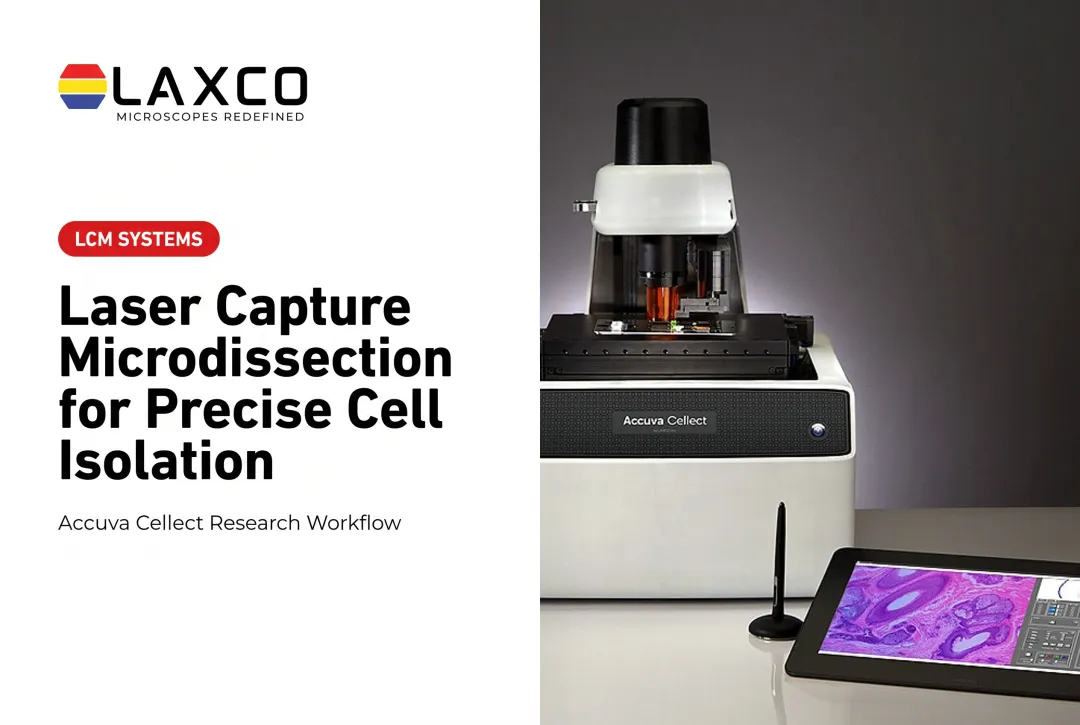
Laxco's Accuva Cellect Laser Capture Microdissection System is designed for this upstream step. It combines two laser functions:
- An infrared (IR) laser designed for film capture of single cells or small numbers of cells.
- An ultraviolet (UV) laser designed for cutting dense structures, such as bone or plant tissue.
- Laxco documentation lists support for FFPE and fresh-frozen samples, H&E-stained and LCM-optimized stains, immunofluorescence, unstained samples, and cell culture.
- A five-step software workflow supports target selection, visual quality control, and documentation.
Accuva Cellect prepares material for downstream DNA or RNA extraction and sequencing. Laxco does not perform sequencing as a laboratory service.
Frequently Asked Questions
How much input DNA does an NGS library need?
Input requirements vary by library-preparation kit, application, and sample quality. Degraded samples, such as some FFPE material, may need protocols designed for low or fragmented input. Check the requirements of your chosen kit before planning sample collection.
When is long-read sequencing a better fit than short-read sequencing?
Long reads can help with structural variants, repetitive regions, and de novo assembly. Short reads are widely used for variant detection and expression studies at high throughput. The choice depends on the biological question, budget, and required accuracy.
How do I sequence only one cell population from a tissue section?
One option is to isolate the target cells before extraction using laser capture microdissection. The selected region is identified under the microscope, captured, and processed for DNA or RNA. Laxco's Accuva Cellect is designed for this workflow.
Which sample types can be used with Accuva Cellect?
Laxco lists FFPE and fresh-frozen tissue, H&E-stained and LCM-optimized stained sections, immunofluorescence, unstained samples, and cell culture. Compatibility with your downstream extraction and sequencing protocol should be confirmed during workflow planning.
What support does Laxco provide for Accuva Cellect users?
Laxco offers on-site and virtual application training and live technical support for Accuva Cellect. The product page also states a 48-hour response commitment for support requests.